> ## Documentation Index
> Fetch the complete documentation index at: https://mintlify-poc.mintlify.site/llms.txt
> Use this file to discover all available pages before exploring further.
# Sync data from Postgres
> Sync updates to your primary Postgres database with Tiger Cloud in real time
export const COMPANY = 'Tiger Data ';
export const COLUMNSTORE = 'columnstore';
export const CLOUD_LONG = 'Tiger Cloud';
export const SERVICE_SHORT = 'service';
export const CONSOLE = 'Tiger Console';
export const PG_CONNECTOR_0 = undefined;
export const HYPERTABLE = 'hypertable';
export const TIMESCALE_DB = 'TimescaleDB';
export const PG_CONNECTOR = 'source Postgres connector';
export const PG = 'Postgres';
export const CAGG = 'continuous aggregate';
export const SERVICE_LONG = 'Tiger Cloud service';
Early access
You use the {PG_CONNECTOR} in {CLOUD_LONG} to synchronize all data or specific tables from a {PG} database instance to your {SERVICE_SHORT}, in real time. You run the connector continuously, turning {PG} into a primary database with your {SERVICE_SHORT} as a logical replica. This enables you to leverage {CLOUD_LONG}'s real-time analytics capabilities on your replica data.
![CLOUD\_LONG connectors overview][cloud_long-connectors-overview]
The {PG_CONNECTOR} in {CLOUD_LONG} leverages the well-established {PG} logical replication protocol. By relying on this protocol, {CLOUD_LONG} ensures compatibility, familiarity, and a broader knowledge base—making it easier for you to adopt the connector and integrate your data.
You use the {PG_CONNECTOR} for data synchronization, rather than migration. This includes:
* Copy existing data from a {PG} instance to a {SERVICE_LONG}:
* Copy data at up to 150 GB/hr.
You need at least a 4 CPU/16 GB source database, and a 4 CPU/16 GB target {SERVICE_SHORT}.
* Copy the publication tables in parallel.
Large tables are still copied using a single connection. Parallel copying is in the backlog.
* Forget foreign key relationships.
The connector disables foreign key validation during the sync. For example, if a `metrics` table refers to the `id` column on the `tags` table, you can still sync only the `metrics` table without worrying about their foreign key relationships.
* Track progress.
{PG} exposes `COPY` progress under `pg_stat_progress_copy`.
* Synchronize real-time changes from a {PG} instance to a {SERVICE_LONG}.
* Add and remove tables on demand using the [{PG} PUBLICATION interface][create-publication].
* Enable features such as [{HYPERTABLE}s][hypertables-section], [{COLUMNSTORE}][compression], and [{CAGG}s][caggs] on your logical replica.
This {PG_CONNECTOR} is not yet supported for production use. If you have any questions or feedback, talk to us in #livesync in the {COMPANY} Community.
## Prerequisites
To follow the steps on this page:
* Create a target [{SERVICE_LONG}][create-service] with Real-time analytics enabled.
You need your [connection details][connection-info].
[connection-info]: /integrations/find-connection-details
[create-service]: /deploy-and-operate/tiger-cloud/get-started/create-services
* Install the [{PG} client tools][psql] on your sync machine.
* Ensure that the source {PG} instance and the target {SERVICE_LONG} have the same extensions installed.
The {PG_CONNECTOR} does not create extensions on the target. If the table uses column types from an extension, first create the extension on the target {SERVICE_LONG} before syncing the table.
## Limitations
* The source {PG} instance must be accessible from the Internet.
Services hosted behind a firewall or VPC are not supported. This functionality is on the roadmap.
* Indexes, including the primary key, unique constraints, and sequences are not migrated to the target {SERVICE_LONG}.
We recommend that, depending on your query patterns, you create only the necessary indexes on the target {SERVICE_LONG}.
- Using {TIMESCALE_DB} as the source has limited support (no {CAGG}s).
- The source must be running {PG} 13 or later.
- Schema changes must be co-ordinated.
Make compatible changes to the schema in your {SERVICE_LONG} first, then make the same changes to the source {PG} instance.
- Ensure that the source {PG} instance and the target {SERVICE_LONG} have the same extensions installed.
The {PG_CONNECTOR} does not create extensions on the target. If the table uses column types from an extension, first create the extension on the target {SERVICE_LONG} before syncing the table.
- There is WAL volume growth on the source {PG} instance during large table copy.
- Continuous aggregate invalidation
The connector uses `session_replication_role=replica` during data replication, which prevents table triggers from firing. This includes the internal triggers that mark {CAGG}s as invalid when underlying data changes.
If you have {CAGG}s on your target database, they do not automatically refresh for data inserted during the migration. This limitation only applies to data below the {CAGG}'s materialization watermark. For example, backfilled data. New rows synced above the {CAGG} watermark are used correctly when refreshing.
This can lead to:
* Missing data in {CAGG}s for the migration period.
* Stale aggregate data.
* Queries returning incomplete results.
If the {CAGG} exists in the source database, best practice is to add it to the {PG} connector publication. If it only exists on the target database, manually refresh the {CAGG} using the `force` option of [refresh\_continuous\_aggregate][refresh-caggs].
[refresh-caggs]: /api-reference/timescaledb/continuous-aggregates/refresh_continuous_aggregate#samples
## Set your connection string
This variable holds the connection information for the source database. In the terminal on your migration machine, set the following:
```bash theme={"dark"}
export SOURCE="postgres://:@:/"
```
Avoid using connection strings that route through connection poolers like PgBouncer or similar tools. This tool requires a direct connection to the database to function properly.
## Tune your source database
Updating parameters on a {PG} instance will cause an outage. Choose a time that will cause the least issues to tune this database.
1. **Tune the Write Ahead Log (WAL) on the RDS/Aurora {PG} source database**
1. In [https://console.aws.amazon.com/rds/home#databases:][databases], select the RDS instance to migrate.
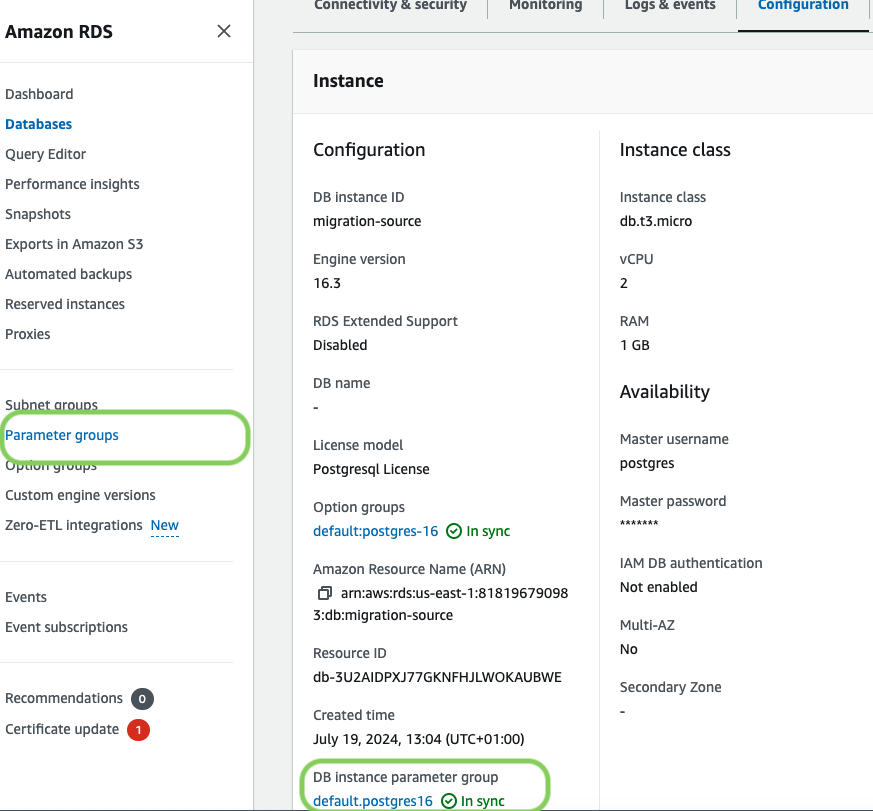
2. Click `Configuration`, scroll down and note the `DB instance parameter group`, then click `Parameter Groups`
3. Click `Create parameter group`, fill in the form with the following values, then click `Create`.
* **Parameter group name** - whatever suits your fancy.
* **Description** - knock yourself out with this one.
* **Engine type** - `PostgreSQL`
* **Parameter group family** - the same as `DB instance parameter group` in your `Configuration`.
4. In `Parameter groups`, select the parameter group you created, then click `Edit`.
5. Update the following parameters, then click `Save changes`.
* `rds.logical_replication` set to `1`: record the information needed for logical decoding.
* `wal_sender_timeout` set to `0`: disable the timeout for the sender process.
6. In RDS, navigate back to your [databases][databases], select the RDS instance to migrate, and click `Modify`.
7. Scroll down to `Database options`, select your new parameter group, and click `Continue`.
8. Click `Apply immediately` or choose a maintenance window, then click `Modify DB instance`.
Changing parameters will cause an outage. Wait for the database instance to reboot before continuing.
9. Verify that the settings are live in your database.
2. **Create a user for the {PG_CONNECTOR_0} and assign permissions**
1. Create ``:
```sql theme={"dark"}
psql $SOURCE -c "CREATE USER PASSWORD ''"
```
You can use an existing user. However, you must ensure that the user has the following permissions.
2. Grant permissions to create a replication slot:
```sql theme={"dark"}
psql $SOURCE -c "GRANT rds_replication TO "
```
3. Grant permissions to create a publication:
```sql theme={"dark"}
psql $SOURCE -c "GRANT CREATE ON DATABASE TO "
```
4. Assign the user permissions on the source database:
```sql theme={"dark"}
psql $SOURCE <;
GRANT SELECT ON ALL TABLES IN SCHEMA "public" TO ;
ALTER DEFAULT PRIVILEGES IN SCHEMA "public" GRANT SELECT ON TABLES TO ;
EOF
```
If the tables you are syncing are not in the `public` schema, grant the user permissions for each schema you are syncing:
```sql theme={"dark"}
psql $SOURCE < TO ;
GRANT SELECT ON ALL TABLES IN SCHEMA TO ;
ALTER DEFAULT PRIVILEGES IN SCHEMA GRANT SELECT ON TABLES TO ;
EOF
```
5. On each table you want to sync, make `` the owner:
```sql theme={"dark"}
psql $SOURCE -c 'ALTER TABLE
OWNER TO ;'
```
You can skip this step if the replicating user is already the owner of the tables.
3. **Enable replication `DELETE` and`UPDATE` operations**
Replica identity assists data replication by identifying the rows being modified. Your options are that each table and {HYPERTABLE} in the source database should either have:
* **A primary key**: data replication defaults to the primary key of the table being replicated. Nothing to do.
* **A viable unique index**: each table has a unique, non-partial, non-deferrable index that includes only columns marked as `NOT NULL`. If a UNIQUE index does not exist, create one to assist the migration. You can delete if after migration.
For each table, set `REPLICA IDENTITY` to the viable unique index:
```shell theme={"dark"}
psql -X -d $SOURCE -c 'ALTER TABLE
REPLICA IDENTITY USING INDEX <_index_name>'
```
* **No primary key or viable unique index**: use brute force.
For each table, set `REPLICA IDENTITY` to `FULL`:
```shell theme={"dark"}
psql -X -d $SOURCE -c 'ALTER TABLE {table_name} REPLICA IDENTITY FULL'
```
For each `UPDATE` or `DELETE` statement, {PG} reads the whole table to find all matching rows. This results in significantly slower replication. If you are expecting a large number of `UPDATE` or `DELETE` operations on the table, best practice is to not use `FULL`.
[databases]: https://console.aws.amazon.com/rds/home#databases:
1. **Tune the Write Ahead Log (WAL) on the {PG} source database**
```sql theme={"dark"}
psql $SOURCE <`:
```sql theme={"dark"}
psql $SOURCE -c "CREATE USER PASSWORD ''"
```
You can use an existing user. However, you must ensure that the user has the following permissions.
2. Grant permissions to create a replication slot:
```sql theme={"dark"}
psql $SOURCE -c "ALTER ROLE REPLICATION"
```
3. Grant permissions to create a publication:
```sql theme={"dark"}
psql $SOURCE -c "GRANT CREATE ON DATABASE TO "
```
4. Assign the user permissions on the source database:
```sql theme={"dark"}
psql $SOURCE <;
GRANT SELECT ON ALL TABLES IN SCHEMA "public" TO ;
ALTER DEFAULT PRIVILEGES IN SCHEMA "public" GRANT SELECT ON TABLES TO ;
EOF
```
If the tables you are syncing are not in the `public` schema, grant the user permissions for each schema you are syncing:
```sql theme={"dark"}
psql $SOURCE < TO ;
GRANT SELECT ON ALL TABLES IN SCHEMA TO ;
ALTER DEFAULT PRIVILEGES IN SCHEMA GRANT SELECT ON TABLES TO ;
EOF
```
5. On each table you want to sync, make `` the owner:
```sql theme={"dark"}
psql $SOURCE -c 'ALTER TABLE
OWNER TO ;'
```
You can skip this step if the replicating user is already the owner of the tables.
3. **Enable replication `DELETE` and`UPDATE` operations**
Replica identity assists data replication by identifying the rows being modified. Your options are that each table and {HYPERTABLE} in the source database should either have:
* **A primary key**: data replication defaults to the primary key of the table being replicated. Nothing to do.
* **A viable unique index**: each table has a unique, non-partial, non-deferrable index that includes only columns marked as `NOT NULL`. If a UNIQUE index does not exist, create one to assist the migration. You can delete if after migration.
For each table, set `REPLICA IDENTITY` to the viable unique index:
```shell theme={"dark"}
psql -X -d $SOURCE -c 'ALTER TABLE
REPLICA IDENTITY USING INDEX <_index_name>'
```
* **No primary key or viable unique index**: use brute force.
For each table, set `REPLICA IDENTITY` to `FULL`:
```shell theme={"dark"}
psql -X -d $SOURCE -c 'ALTER TABLE {table_name} REPLICA IDENTITY FULL'
```
For each `UPDATE` or `DELETE` statement, {PG} reads the whole table to find all matching rows. This results in significantly slower replication. If you are expecting a large number of `UPDATE` or `DELETE` operations on the table, best practice is to not use `FULL`.
[guc-max_wal_senders-as-10]: https://www.postgresql.org/docs/current/runtime-config-replication.html#GUC-MAX-WAL-SENDERS
[guc-wal_level-as-logical]: https://www.postgresql.org/docs/current/runtime-config-wal.html#GUC-WAL-LEVEL
[guc-wal_sender_timeout-as-0]: https://www.postgresql.org/docs/current/runtime-config-replication.html#GUC-WAL-SENDER-TIMEOUT
## Synchronize data to your service
To sync data from your {PG} database to your {SERVICE_LONG} using {CONSOLE}:
1. **Connect to your {SERVICE_LONG}**
In [{CONSOLE}][services-portal], select the {SERVICE_SHORT} to sync live data to.
2. **Connect the source database and the target {SERVICE_SHORT}**
![Postgres connector wizard][postgres-connector-wizard]
1. Click `Connectors` > `PostgreSQL`.
2. Set the name for the new connector by clicking the pencil icon.
3. Check the boxes for `Set wal_level to logical` and `Update your credentials`, then click `Continue`.
4. Enter your database credentials or a {PG} connection string, then click `Connect to database`.
This is the connection string for [``][livesync-tune-source-db]. {CONSOLE} connects to the source database and retrieves the schema information.
3. **Optimize the data to synchronize in hypertables**
![Postgres connector start][postgres-connector-start]
1. In the `Select table` dropdown, select the tables to sync.
2. Click `Select tables +` .
{CONSOLE} checks the table schema and, if possible, suggests the column to use as the time dimension in a {HYPERTABLE}.
3. Click `Create Connector`.
{CONSOLE} starts {PG_CONNECTOR} between the source database and the target {SERVICE_SHORT} and displays the progress.
4. **Monitor synchronization**
![Tiger connectors overview][tiger-connectors-overview]
1. To view the amount of data replicated, click `Connectors`. The diagram in `Connector data flow` gives you an overview of the connectors you have created, their status, and how much data has been replicated.
2. To review the syncing progress for each table, click `Connectors` > `Source connectors`, then select the name of your connector in the table.
5. **Manage the connector**
![Edit a Postgres connector][edit-a-postgres-connector]
1. To edit the connector, click `Connectors` > `Source connectors`, then select the name of your connector in the table. You can rename the connector, delete or add new tables for syncing.
2. To pause a connector, click `Connectors` > `Source connectors`, then open the three-dot menu on the right and select `Pause`.
3. To delete a connector, click `Connectors` > `Source connectors`, then open the three-dot menu on the right and select `Delete`. You must pause the connector before deleting it.
And that is it, you are using the {PG_CONNECTOR} to synchronize all the data, or specific tables, from a {PG} database instance to your {SERVICE_LONG}, in real time.
[edit-a-postgres-connector]: https://assets.timescale.com/docs/images/tiger-on-azure/edit-pg-connector-tiger-console.png
[livesync-tune-source-db]: /integrations/connectors/source/sync-from-postgres#tune-your-source-database
[postgres-connector-start]: https://assets.timescale.com/docs/images/tiger-on-azure/pg-connector-start-tiger-console.png
[postgres-connector-wizard]: https://assets.timescale.com/docs/images/tiger-on-azure/pg-connector-wizard-tiger-console.png
[psql]: /integrations/query-administration/psql
[services-portal]: https://console.cloud.timescale.com/dashboard/services
[tiger-connectors-overview]: https://assets.timescale.com/docs/images/tiger-on-azure/tiger-console-connector-overview.png
## Prerequisites
Best practice is to use an [Ubuntu EC2 instance][create-ec2-instance] hosted in the same region as your {SERVICE_LONG} to move data. That is, the machine you run the commands on to move your data from your source database to your target {SERVICE_LONG}.
Before you move your data:
* Create a target [{SERVICE_LONG}][create-service].
Each {SERVICE_LONG} has a single {PG} instance that supports the [most popular extensions][all-available-extensions]. {SERVICE_LONG}s do not support tablespaces, and there is no superuser associated with a {SERVICE_SHORT}.
Best practice is to create a {SERVICE_LONG} with at least 8 CPUs for a smoother experience. A higher-spec instance can significantly reduce the overall migration window.
* To ensure that maintenance does not run while migration is in progress, best practice is to [adjust the maintenance window][adjust-maintenance-window].
[adjust-maintenance-window]: /open-source/timescaledb/upgrades#define-your-maintenance-window
[all-available-extensions]: /open-source/timescaledb/extensions
[create-ec2-instance]: https://docs.aws.amazon.com/AWSEC2/latest/UserGuide/EC2_GetStarted.html#ec2-launch-instance
[create-service]: /getting-started/services
* Ensure that the source {PG} instance and the target {SERVICE_LONG} have the same extensions installed.
The {PG_CONNECTOR} does not create extensions on the target. If the table uses column types from an extension, first create the extension on the target {SERVICE_LONG} before syncing the table.
* [Install Docker][install-docker] on your sync machine.
For a better experience, use a 4 CPU/16GB EC2 instance or greater to run the {PG_CONNECTOR}.
* Install the [{PG} client tools][psql] on your sync machine.
This includes `psql`, `pg_dump`, `pg_dumpall`, and `vacuumdb` commands.
## Limitations
* The schema is not migrated by the {PG_CONNECTOR}, you use `pg_dump`/`pg_restore` to migrate it.
- Using {TIMESCALE_DB} as the source has limited support (no {CAGG}s).
- The source must be running {PG} 13 or later.
- Schema changes must be co-ordinated.
Make compatible changes to the schema in your {SERVICE_LONG} first, then make the same changes to the source {PG} instance.
- Ensure that the source {PG} instance and the target {SERVICE_LONG} have the same extensions installed.
The {PG_CONNECTOR} does not create extensions on the target. If the table uses column types from an extension, first create the extension on the target {SERVICE_LONG} before syncing the table.
- There is WAL volume growth on the source {PG} instance during large table copy.
- Continuous aggregate invalidation
The connector uses `session_replication_role=replica` during data replication, which prevents table triggers from firing. This includes the internal triggers that mark {CAGG}s as invalid when underlying data changes.
If you have {CAGG}s on your target database, they do not automatically refresh for data inserted during the migration. This limitation only applies to data below the {CAGG}'s materialization watermark. For example, backfilled data. New rows synced above the {CAGG} watermark are used correctly when refreshing.
This can lead to:
* Missing data in {CAGG}s for the migration period.
* Stale aggregate data.
* Queries returning incomplete results.
If the {CAGG} exists in the source database, best practice is to add it to the {PG} connector publication. If it only exists on the target database, manually refresh the {CAGG} using the `force` option of [refresh\_continuous\_aggregate][refresh-caggs].
[refresh-caggs]: /api-reference/timescaledb/continuous-aggregates/refresh_continuous_aggregate#samples
## Set your connection strings
The `` in the `SOURCE` connection must have the replication role granted in order to create a replication slot.
These variables hold the connection information for the source database and target {SERVICE_LONG}.
In Terminal on your migration machine, set the following:
```bash theme={"dark"}
export SOURCE="postgres://:@:/"
export TARGET="postgres://tsdbadmin:@:/tsdb?sslmode=require"
```
You find the connection information for your {SERVICE_LONG} in the configuration file you downloaded when you created the service.
Avoid using connection strings that route through connection poolers like PgBouncer or similar tools. This tool requires a direct connection to the database to function properly.
## Tune your source database
Updating parameters on a {PG} instance will cause an outage. Choose a time that will cause the least issues to tune this database.
1. **Tune the Write Ahead Log (WAL) on the RDS/Aurora {PG} source database**
1. In [https://console.aws.amazon.com/rds/home#databases:][databases], select the RDS instance to migrate.
2. Click `Configuration`, scroll down and note the `DB instance parameter group`, then click `Parameter Groups`
3. Click `Create parameter group`, fill in the form with the following values, then click `Create`.
* **Parameter group name** - whatever suits your fancy.
* **Description** - knock yourself out with this one.
* **Engine type** - `PostgreSQL`
* **Parameter group family** - the same as `DB instance parameter group` in your `Configuration`.
4. In `Parameter groups`, select the parameter group you created, then click `Edit`.
5. Update the following parameters, then click `Save changes`.
* `rds.logical_replication` set to `1`: record the information needed for logical decoding.
* `wal_sender_timeout` set to `0`: disable the timeout for the sender process.
6. In RDS, navigate back to your [databases][databases], select the RDS instance to migrate, and click `Modify`.
7. Scroll down to `Database options`, select your new parameter group, and click `Continue`.
8. Click `Apply immediately` or choose a maintenance window, then click `Modify DB instance`.
Changing parameters will cause an outage. Wait for the database instance to reboot before continuing.
9. Verify that the settings are live in your database.
2. **Create a user for the {PG_CONNECTOR_0} and assign permissions**
1. Create ``:
```sql theme={"dark"}
psql $SOURCE -c "CREATE USER PASSWORD ''"
```
You can use an existing user. However, you must ensure that the user has the following permissions.
2. Grant permissions to create a replication slot:
```sql theme={"dark"}
psql $SOURCE -c "GRANT rds_replication TO "
```
3. Grant permissions to create a publication:
```sql theme={"dark"}
psql $SOURCE -c "GRANT CREATE ON DATABASE TO "
```
4. Assign the user permissions on the source database:
```sql theme={"dark"}
psql $SOURCE <;
GRANT SELECT ON ALL TABLES IN SCHEMA "public" TO ;
ALTER DEFAULT PRIVILEGES IN SCHEMA "public" GRANT SELECT ON TABLES TO ;
EOF
```
If the tables you are syncing are not in the `public` schema, grant the user permissions for each schema you are syncing:
```sql theme={"dark"}
psql $SOURCE < TO ;
GRANT SELECT ON ALL TABLES IN SCHEMA TO ;
ALTER DEFAULT PRIVILEGES IN SCHEMA GRANT SELECT ON TABLES TO ;
EOF
```
5. On each table you want to sync, make `` the owner:
```sql theme={"dark"}
psql $SOURCE -c 'ALTER TABLE
OWNER TO ;'
```
You can skip this step if the replicating user is already the owner of the tables.
3. **Enable replication `DELETE` and`UPDATE` operations**
Replica identity assists data replication by identifying the rows being modified. Your options are that each table and {HYPERTABLE} in the source database should either have:
* **A primary key**: data replication defaults to the primary key of the table being replicated. Nothing to do.
* **A viable unique index**: each table has a unique, non-partial, non-deferrable index that includes only columns marked as `NOT NULL`. If a UNIQUE index does not exist, create one to assist the migration. You can delete if after migration.
For each table, set `REPLICA IDENTITY` to the viable unique index:
```shell theme={"dark"}
psql -X -d $SOURCE -c 'ALTER TABLE
REPLICA IDENTITY USING INDEX <_index_name>'
```
* **No primary key or viable unique index**: use brute force.
For each table, set `REPLICA IDENTITY` to `FULL`:
```shell theme={"dark"}
psql -X -d $SOURCE -c 'ALTER TABLE {table_name} REPLICA IDENTITY FULL'
```
For each `UPDATE` or `DELETE` statement, {PG} reads the whole table to find all matching rows. This results in significantly slower replication. If you are expecting a large number of `UPDATE` or `DELETE` operations on the table, best practice is to not use `FULL`.
[databases]: https://console.aws.amazon.com/rds/home#databases:
1. **Tune the Write Ahead Log (WAL) on the {PG} source database**
```sql theme={"dark"}
psql $SOURCE <`:
```sql theme={"dark"}
psql $SOURCE -c "CREATE USER PASSWORD ''"
```
You can use an existing user. However, you must ensure that the user has the following permissions.
2. Grant permissions to create a replication slot:
```sql theme={"dark"}
psql $SOURCE -c "ALTER ROLE REPLICATION"
```
3. Grant permissions to create a publication:
```sql theme={"dark"}
psql $SOURCE -c "GRANT CREATE ON DATABASE TO "
```
4. Assign the user permissions on the source database:
```sql theme={"dark"}
psql $SOURCE <;
GRANT SELECT ON ALL TABLES IN SCHEMA "public" TO ;
ALTER DEFAULT PRIVILEGES IN SCHEMA "public" GRANT SELECT ON TABLES TO ;
EOF
```
If the tables you are syncing are not in the `public` schema, grant the user permissions for each schema you are syncing:
```sql theme={"dark"}
psql $SOURCE < TO ;
GRANT SELECT ON ALL TABLES IN SCHEMA TO ;
ALTER DEFAULT PRIVILEGES IN SCHEMA GRANT SELECT ON TABLES TO ;
EOF
```
5. On each table you want to sync, make `` the owner:
```sql theme={"dark"}
psql $SOURCE -c 'ALTER TABLE
OWNER TO ;'
```
You can skip this step if the replicating user is already the owner of the tables.
3. **Enable replication `DELETE` and`UPDATE` operations**
Replica identity assists data replication by identifying the rows being modified. Your options are that each table and {HYPERTABLE} in the source database should either have:
* **A primary key**: data replication defaults to the primary key of the table being replicated. Nothing to do.
* **A viable unique index**: each table has a unique, non-partial, non-deferrable index that includes only columns marked as `NOT NULL`. If a UNIQUE index does not exist, create one to assist the migration. You can delete if after migration.
For each table, set `REPLICA IDENTITY` to the viable unique index:
```shell theme={"dark"}
psql -X -d $SOURCE -c 'ALTER TABLE
REPLICA IDENTITY USING INDEX <_index_name>'
```
* **No primary key or viable unique index**: use brute force.
For each table, set `REPLICA IDENTITY` to `FULL`:
```shell theme={"dark"}
psql -X -d $SOURCE -c 'ALTER TABLE {table_name} REPLICA IDENTITY FULL'
```
For each `UPDATE` or `DELETE` statement, {PG} reads the whole table to find all matching rows. This results in significantly slower replication. If you are expecting a large number of `UPDATE` or `DELETE` operations on the table, best practice is to not use `FULL`.
[guc-max_wal_senders-as-10]: https://www.postgresql.org/docs/current/runtime-config-replication.html#GUC-MAX-WAL-SENDERS
[guc-wal_level-as-logical]: https://www.postgresql.org/docs/current/runtime-config-wal.html#GUC-WAL-LEVEL
[guc-wal_sender_timeout-as-0]: https://www.postgresql.org/docs/current/runtime-config-replication.html#GUC-WAL-SENDER-TIMEOUT
## Migrate the table schema to the service
Use `pg_dump` to:
1. **Download the schema from the source database**
```shell theme={"dark"}
pg_dump $SOURCE \
--no-privileges \
--no-owner \
--no-publications \
--no-subscriptions \
--no-table-access-method \
--no-tablespaces \
--schema-only \
--file=schema.sql
```
2. **Apply the schema on the target {SERVICE_SHORT}**
```shell theme={"dark"}
psql $TARGET -f schema.sql
```
## Convert partitions and tables with time-series data into hypertables
For efficient querying and analysis, you can convert tables which contain time-series or events data, and tables that are already partitioned using {PG} declarative partition into [{HYPERTABLE}s][hypertables-section].
1. **Convert tables to hypertables**
Run the following on each table in the target {SERVICE_LONG} to convert it to a {HYPERTABLE}:
```shell theme={"dark"}
psql -X -d $TARGET -c "SELECT public.create_hypertable('
', by_range('', ''::interval));"
```
For example, to convert the *metrics* table into a {HYPERTABLE} with *time* as a partition column and *1 day* as a partition interval:
```shell theme={"dark"}
psql -X -d $TARGET -c "SELECT public.create_hypertable('public.metrics', by_range('time', '1 day'::interval));"
```
2. **Convert {PG} partitions to hypertables**
Rename the partition and create a new regular table with the same name as the partitioned table, then convert to a {HYPERTABLE}:
```shell theme={"dark"}
psql $TARGET -f - <<'EOF'
BEGIN;
ALTER TABLE public.events RENAME TO events_part;
CREATE TABLE public.events(LIKE public.events_part INCLUDING ALL);
SELECT create_hypertable('public.events', by_range('time', '1 day'::interval));
COMMIT;
EOF
```
## Specify the tables to synchronize
After the schema is migrated, you [`CREATE PUBLICATION`][create-publication] on the source database that specifies the tables to synchronize.
1. **Create a publication that specifies the table to synchronize**
A `PUBLICATION` enables you to synchronize some or all the tables in the schema or database.
```sql theme={"dark"}
CREATE PUBLICATION FOR TABLE , ;
```
To add tables after to an existing publication, use [ALTER PUBLICATION][alter-publication]
```sql theme={"dark"}
ALTER PUBLICATION ADD TABLE ;
```
2. **Publish the {PG} declarative partitioned table**
```sql theme={"dark"}
ALTER PUBLICATION SET(publish_via_partition_root=true);
```
To convert a partitioned table to a {HYPERTABLE}, follow [Convert partitions and tables with time-series data into {HYPERTABLE}s][convert-partitions-and-tables-with-time-series-data-into-hypertables-link].
3. **Stop syncing a table in the `PUBLICATION`, use `DROP TABLE`**
```sql theme={"dark"}
ALTER PUBLICATION DROP TABLE ;
```
## Synchronize data to your service
You use the {PG_CONNECTOR} docker image to synchronize changes in real time from a {PG} database instance to a {SERVICE_LONG}:
1. **Start the {PG_CONNECTOR}**
As you run the {PG_CONNECTOR} continuously, best practice is to run it as a Docker daemon.
```shell theme={"dark"}
docker run -d --rm --name livesync timescale/live-sync:v0.4.0 run \
--publication --subscription \
--source $SOURCE --target $TARGET --table-map
```
`--publication`: The name of the publication as you created in the previous step. To use multiple publications, repeat the `--publication` flag.
`--subscription`: The name that identifies the subscription on the target {SERVICE_LONG}.
`--source`: The connection string to the source {PG} database.
`--target`: The connection string to the target {SERVICE_LONG}.
`--table-map`: (Optional) A JSON string that maps source tables to target tables. If not provided, the source and target table names are assumed to be the same.
For example, to map the source table `metrics` to the target table `metrics_data`:
`--table-sync-workers`: (Optional) The number of parallel workers to use for initial table sync. Default is 4.
`--copy-data`: (Optional) By default, the initial table data is copied from source to target before starting logical replication. Set to `false` so only changes made after replication slot creation are replicated.
Best practice is to set to `false` during dry-run livesync so you do not copy table data.
```
--table-map '{"source": {"schema": "public", "table": "metrics"}, "target": {"schema": "public", "table": "metrics_data"}}'
```
To map only the schema, use:
```
--table-map '{"source": {"schema": "public"}, "target": {"schema": "analytics"}}'
```
This flag can be repeated for multiple table mappings.
2. **Capture logs**
Once the {PG_CONNECTOR} is running as a docker daemon, you can also capture the logs:
```shell theme={"dark"}
docker logs -f livesync
```
3. **View the progress of tables being synchronized**
List the tables being synchronized by the {PG_CONNECTOR} using the `_ts_live_sync.subscription_rel` table in the target {SERVICE_LONG}:
```bash theme={"dark"}
psql $TARGET -c "SELECT * FROM _ts_live_sync.subscription_rel"
```
You see something like the following:
| subname | pubname | schemaname | tablename | rrelid | state | lsn | updated\_at | last\_error | created\_at | rows\_copied | approximate\_rows | bytes\_copied | approximate\_size | target\_schema | target\_table |
| -------- | --------- | ---------- | --------- | ------ | ----- | ---------- | ----------------------------- | ----------- | ----------------------------- | ------------ | ----------------- | ------------- | ----------------- | -------------- | ------------- |
| livesync | analytics | public | metrics | 20856 | r | 6/1A8CBA48 | 2025-06-24 06:16:21.434898+00 | | 2025-06-24 06:03:58.172946+00 | 18225440 | 18225440 | 1387359359 | 1387359359 | public | metrics |
The `state` column indicates the current state of the table synchronization.
Possible values for `state` are:
| state | description |
| ----- | ------------------------------------ |
| d | initial table data sync |
| f | initial table data sync completed |
| s | catching up with the latest changes |
| r | table is ready, syncing live changes |
To see the replication lag, run the following against the SOURCE database:
```bash theme={"dark"}
psql $SOURCE -f - <<'EOF'
SELECT
slot_name,
pg_size_pretty(pg_current_wal_flush_lsn() - confirmed_flush_lsn) AS lag
FROM pg_replication_slots
WHERE slot_name LIKE 'live_sync_%' AND slot_type = 'logical'
EOF
```
4. **Add or remove tables from the publication**
To add tables, use [ALTER PUBLICATION .. ADD TABLE][alter-publication]
```sql theme={"dark"}
ALTER PUBLICATION ADD TABLE ;
```
To remove tables, use [ALTER PUBLICATION .. DROP TABLE][alter-publication]
```sql theme={"dark"}
ALTER PUBLICATION DROP TABLE ;
```
5. **Update table statistics**
If you have a large table, you can run `ANALYZE` on the target {SERVICE_LONG} to update the table statistics after the initial sync is complete.
This helps the query planner make better decisions for query execution plans.
```bash theme={"dark"}
vacuumdb --analyze --verbose --dbname=$TARGET
```
6. **Stop the {PG_CONNECTOR}**
```shell theme={"dark"}
docker stop live-sync
```
7. **(Optional) Reset sequence nextval on the target {SERVICE_LONG}**
The {PG_CONNECTOR} does not automatically reset the sequence nextval on the target {SERVICE_LONG}.
Run the following script to reset the sequence for all tables that have a serial or identity column in the target {SERVICE_LONG}:
```bash theme={"dark"}
psql $TARGET -f - <<'EOF'
DO $$
DECLARE
rec RECORD;
BEGIN
FOR rec IN (
SELECT
sr.target_schema AS table_schema,
sr.target_table AS table_name,
col.column_name,
pg_get_serial_sequence(
sr.target_schema || '.' || sr.target_table,
col.column_name
) AS seqname
FROM _ts_live_sync.subscription_rel AS sr
JOIN information_schema.columns AS col
ON col.table_schema = sr.target_schema
AND col.table_name = sr.target_table
WHERE col.column_default LIKE 'nextval(%' -- only serial/identity columns
) LOOP
EXECUTE format(
'SELECT setval(%L,
COALESCE((SELECT MAX(%I) FROM %I.%I), 0) + 1,
false
);',
rec.seqname, -- the sequence identifier
rec.column_name, -- the column to MAX()
rec.table_schema, -- schema for MAX()
rec.table_name -- table for MAX()
);
END LOOP;
END;
$$ LANGUAGE plpgsql;
EOF
```
8. **Clean up**
Use the `--drop` flag to remove the replication slots created by the {PG_CONNECTOR} on the source database.
```shell theme={"dark"}
docker run -it --rm --name livesync timescale/live-sync:v0.4.0 run \
--publication --subscription \
--source $SOURCE --target $TARGET \
--drop
```
[alter-publication]: https://www.postgresql.org/docs/current/sql-alterpublication.html
[convert-partitions-and-tables-with-time-series-data-into-hypertables-link]: /integrations/connectors/source/sync-from-postgres#convert-partitions-and-tables-with-time-series-data-into-hypertables
[create-publication]: https://www.postgresql.org/docs/current/sql-createpublication.html
[hypertables-section]: /open-source/timescaledb/hypertables
[install-docker]: https://docs.docker.com/engine/install/
[psql]: /integrations/query-administration/psql
[caggs]: /open-source/timescaledb/continuous-aggregates
[cloud_long-connectors-overview]: https://assets.timescale.com/docs/images/tiger-on-azure/tiger-console-connector-overview.png
[compression]: /open-source/timescaledb/compression
[create-publication]: https://www.postgresql.org/docs/current/sql-createpublication.html
[hypertables-section]: /open-source/timescaledb/hypertables
 3. Click `Create parameter group`, fill in the form with the following values, then click `Create`.
* **Parameter group name** - whatever suits your fancy.
* **Description** - knock yourself out with this one.
* **Engine type** - `PostgreSQL`
* **Parameter group family** - the same as `DB instance parameter group` in your `Configuration`.
4. In `Parameter groups`, select the parameter group you created, then click `Edit`.
5. Update the following parameters, then click `Save changes`.
* `rds.logical_replication` set to `1`: record the information needed for logical decoding.
* `wal_sender_timeout` set to `0`: disable the timeout for the sender process.
6. In RDS, navigate back to your [databases][databases], select the RDS instance to migrate, and click `Modify`.
7. Scroll down to `Database options`, select your new parameter group, and click `Continue`.
8. Click `Apply immediately` or choose a maintenance window, then click `Modify DB instance`.
Changing parameters will cause an outage. Wait for the database instance to reboot before continuing.
9. Verify that the settings are live in your database.
2. **Create a user for the {PG_CONNECTOR_0} and assign permissions**
1. Create `