> ## Documentation Index
> Fetch the complete documentation index at: https://mintlify-poc.mintlify.site/llms.txt
> Use this file to discover all available pages before exploring further.
# Analyze financial tick data
> Store financial tick data and create candlestick views for real-time analysis of price changes
export const CAGG = 'continuous aggregate';
export const SELF_LONG = 'self-hosted TimescaleDB';
export const CONSOLE = 'Tiger Console';
export const HYPERTABLE_CAP = 'Hypertable';
export const HYPERCORE = 'hypercore';
export const ROWSTORE = 'rowstore';
export const HYPERCORE_CAP = 'Hypercore';
export const CHUNK = 'chunk';
export const HYPERTABLE = 'hypertable';
export const COLUMNSTORE = 'columnstore';
export const TIMESCALE_DB = 'TimescaleDB';
export const COMPANY = 'Tiger Data ';
export const PG = 'Postgres';
export const SERVICE_SHORT = 'service';
export const SERVICE_LONG = 'Tiger Cloud service';
The financial industry is extremely data-heavy and relies on real-time and historical data for decision-making, risk assessment, fraud detection, and market analysis. {COMPANY} simplifies management of these large volumes of data, while also providing you with meaningful analytical insights and optimizing storage costs.
To analyze financial data, you can chart the open, high, low, close, and volume
(OHLCV) information for a financial asset. Using this data, you can create
candlestick charts that make it easier to analyze the price changes of financial
assets over time. You can use candlestick charts to examine trends in stock,
cryptocurrency, or NFT prices.
In this tutorial, you use real raw financial data provided by
[Twelve Data][twelve-data], create an aggregated candlestick view, query the
aggregated data, and visualize the data in Grafana.
This tutorial covers:
1. **Ingest data into a {SERVICE_SHORT}**: load data from [Twelve Data][twelve-data] into your {TIMESCALE_DB} database.
2. **Query your dataset**: create candlestick views, query the aggregated data, and visualize the data in Grafana.
## Prerequisites
To follow the steps on this page:
* Create a target [{SERVICE_LONG}][create-service] with Real-time analytics enabled.
You need [your connection details][connection-info]. This procedure also
works for [{SELF_LONG}][enable-timescaledb].
[create-service]: /deploy-and-operate/tiger-cloud/get-started/create-services
[enable-timescaledb]: /deploy-and-operate/self-hosted/install-and-update/install-self-hosted
[connection-info]: /integrations/find-connection-details
* Install and run [self-managed Grafana][grafana-self-managed], or sign up for [Grafana Cloud][grafana-cloud].
This tutorial uses a dataset that contains second-by-second trade data for
the most-traded crypto-assets. You optimize this time-series data in a {HYPERTABLE} called `crypto_ticks`.
You also create a separate table of asset symbols in a regular {PG} table named `crypto_assets`.
## OHLCV data and candlestick charts
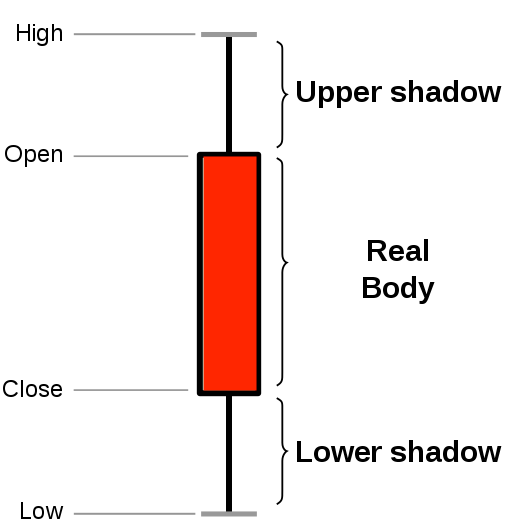
The financial sector regularly uses [candlestick charts][charts] to visualize
the price change of an asset. Each candlestick represents a time period, such as
one minute or one hour, and shows how the asset's price changed during that time.
Candlestick charts are generated from the open, high, low, close, and volume
data for each financial asset during the time period. This is often abbreviated
as OHLCV:
* Open: opening price
* High: highest price
* Low: lowest price
* Close: closing price
* Volume: volume of transactions
[charts]: https://www.investopedia.com/terms/c/candlestick.asp
{TIMESCALE_DB} is well suited to storing and analyzing financial candlestick data,
and many {COMPANY} community members use it for exactly this purpose. Check out
these stories from some {COMPANY} community members:
* [How Trading Strategy built a data stack for crypto quant trading][trading-strategy]
* [How Messari uses data to open the cryptoeconomy to everyone][messari]
* [How I power a (successful) crypto trading bot with {TIMESCALE_DB}][bot]
## Optimize time-series data in a hypertable
{HYPERTABLE_CAP}s are {PG} tables in {TIMESCALE_DB} that automatically partition your time-series data by time. Time-series data represents the way a system, process, or behavior changes over time. {HYPERTABLE_CAP}s enable {TIMESCALE_DB} to work efficiently with time-series data. Each {HYPERTABLE} is made up of child tables called chunks. Each chunk is assigned a range of time, and only contains data from that range. When you run a query, {TIMESCALE_DB} identifies the correct chunk and runs the query on it, instead of going through the entire table.
[{HYPERCORE_CAP}][hypercore] is the hybrid row-columnar storage engine in {TIMESCALE_DB} used by {HYPERTABLE}s. Traditional
databases force a trade-off between fast inserts (row-based storage) and efficient analytics
(columnar storage). {HYPERCORE_CAP} eliminates this trade-off, allowing real-time analytics without sacrificing
transactional capabilities.
{HYPERCORE_CAP} dynamically stores data in the most efficient format for its lifecycle:
![Move from rowstore to columstore in hypercore][move-from-rowstore-to-columstore-in-hypercore]
* **Row-based storage for recent data**: the most recent chunk (and possibly more) is always stored in the {ROWSTORE},
ensuring fast inserts, updates, and low-latency single record queries. Additionally, row-based storage is used as a
writethrough for inserts and updates to columnar storage.
* **Columnar storage for analytical performance**: chunks are automatically compressed into the {COLUMNSTORE}, optimizing
storage efficiency and accelerating analytical queries.
Unlike traditional columnar databases, {HYPERCORE} allows data to be inserted or modified at any stage, making it a
flexible solution for both high-ingest transactional workloads and real-time analytics—within a single database.
[hypercore]: /manage-data/capabilities/hypercore/understand-hypercore
[move-from-rowstore-to-columstore-in-hypercore]: https://assets.timescale.com/docs/images/hypercore_intro.svg
Because {TIMESCALE_DB} is 100% {PG}, you can use all the standard {PG} tables, indexes, stored procedures, and other objects alongside your {HYPERTABLE}s. This makes creating and working with {HYPERTABLE}s similar to standard {PG}.
1. **Connect to your {SERVICE_LONG}**
In [{CONSOLE}][services-portal] open an [SQL editor][in-console-editors]. You can also connect to your service using [psql][psql].
2. **Create a {HYPERTABLE} to store the real-time cryptocurrency data**
Create a [{HYPERTABLE}][hypertables-section] for your time-series data using [CREATE TABLE][hypertable-create-table].
For [efficient queries][secondary-indexes] on data in the {COLUMNSTORE}, remember to `segmentby` the column you will
use most often to filter your data:
```sql theme={"dark"}
CREATE TABLE crypto_ticks (
"time" TIMESTAMPTZ,
symbol TEXT,
price DOUBLE PRECISION,
day_volume NUMERIC
) WITH (
tsdb.hypertable,
tsdb.segmentby='symbol',
tsdb.orderby='time DESC'
);
```
When you create a {HYPERTABLE} using [CREATE TABLE ... WITH ...][hypertable-create-table], the default partitioning
column is automatically the first column with a timestamp data type. Also, {TIMESCALE_DB} creates a
[columnstore policy][add_columnstore_policy] that automatically converts your data to the {COLUMNSTORE}, after an
interval equal to the value of the [chunk\_interval][create_table_arguments], defined through `compress_after` in the
policy. This columnar format enables fast scanning and
aggregation, optimizing performance for analytical workloads while also saving significant storage space. In the
{COLUMNSTORE} conversion, {HYPERTABLE} {CHUNK}s are compressed by up to 98%, and organized for efficient, large-scale queries.
You can customize this policy later using [alter\_job][alter_job_samples]. However, to change `after` or
`created_before`, the compression settings, or the {HYPERTABLE} the policy is acting on, you must
[remove the columnstore policy][remove_columnstore_policy] and [add a new one][add_columnstore_policy].
You can also manually [convert {CHUNK}s][convert_to_columnstore] in a {HYPERTABLE} to the {COLUMNSTORE}.
[add_columnstore_policy]: /api-reference/timescaledb/hypercore/add_columnstore_policy
[alter_job_samples]: /api-reference/timescaledb/jobs-automation/alter_job#samples
[convert_to_columnstore]: /api-reference/timescaledb/hypercore/convert_to_columnstore
[create_table_arguments]: /api-reference/timescaledb/hypertables/create_table#arguments
[hypertable-create-table]: /api-reference/timescaledb/hypertables/create_table
[remove_columnstore_policy]: /api-reference/timescaledb/hypercore/remove_columnstore_policy
## Create a standard Postgres table for relational data
When you have relational data that enhances your time-series data, store that data in
standard {PG} relational tables.
1. **Add a table to store the asset symbol and name in a relational table**
```sql theme={"dark"}
CREATE TABLE crypto_assets (
symbol TEXT UNIQUE,
"name" TEXT
);
```
You now have two tables within your {SERVICE_LONG}. A hypertable named `crypto_ticks`, and a normal
{PG} table named `crypto_assets`.
[hypertable-create-table]: /api-reference/timescaledb/hypertables/create_table
[hypercore]: /manage-data/data-management/hypercore/understand-hypercore
[hypertables-section]: /manage-data/data-management/hypertables/understand-hypertables
[in-console-editors]: /deploy-and-operate/tiger-cloud/get-started/run-queries-from-console
[psql]: /integrations/psql
[secondary-indexes]: /use-timescale/hypercore/secondary-indexes
[services-portal]: https://console.cloud.timescale.com/dashboard/services
## Load financial data
This tutorial uses real-time cryptocurrency data, also known as tick data, from
[Twelve Data][twelve-data]. To ingest data into the tables that you created, you need to
download the dataset, then upload the data to your {SERVICE_LONG}.
1. Unzip [crypto\_sample.zip](https://assets.timescale.com/docs/downloads/candlestick/crypto_sample.zip) to a ``.
This test dataset contains second-by-second trade data for the most-traded crypto-assets
and a regular table of asset symbols and company names.
To import up to 100GB of data directly from your current {PG}-based database,
[migrate with downtime][migrate-with-downtime] using native {PG} tooling. To seamlessly import 100GB-10TB+
of data, use the [live migration][migrate-live] tooling supplied by {COMPANY}. To add data from non-{PG}
data sources, see [Import and ingest data][data-ingest].
2. In Terminal, navigate to `` and connect to your {SERVICE_SHORT}.
```bash theme={"dark"}
psql -d "postgres://:@:/"
```
The connection information for a {SERVICE_SHORT} is available in the file you downloaded when you created it.
3. At the `psql` prompt, use the `COPY` command to transfer data into your
{SERVICE_LONG}. If the `.csv` files aren't in your current directory,
specify the file paths in these commands:
```sql theme={"dark"}
\COPY crypto_ticks FROM 'tutorial_sample_tick.csv' CSV HEADER;
```
```sql theme={"dark"}
\COPY crypto_assets FROM 'tutorial_sample_assets.csv' CSV HEADER;
```
Because there are millions of rows of data, the `COPY` process could take a
few minutes depending on your internet connection and local client
resources.
[twelve-data]: https://twelvedata.com/
[migrate-with-downtime]: /migrate/pg-dump-and-restore/
[migrate-live]: /migrate/live-migration/
[data-ingest]: /use-timescale/ingest-data/
## Query the data
Turning raw, real-time tick data into aggregated candlestick views is a common
task for users who work with financial data. {TIMESCALE_DB} includes
[hyperfunctions][hyperfunctions]
that you can use to store and query your financial data more easily.
Hyperfunctions are SQL functions within {TIMESCALE_DB} that make it easier to
manipulate and analyze time-series data in {PG} with fewer lines of code.
There are three hyperfunctions that are essential for calculating candlestick
values: [`time_bucket()`][time-bucket], [`FIRST()`][first], and [`LAST()`][last].
The `time_bucket()` hyperfunction helps you aggregate records into buckets of
arbitrary time intervals based on the timestamp value. `FIRST()` and `LAST()`
help you calculate the opening and closing prices. To calculate highest and
lowest prices, you can use the standard {PG} aggregate functions `MIN` and
`MAX`.
In {TIMESCALE_DB}, the most efficient way to create candlestick views is to use
[continuous aggregates][caggs].
In this tutorial, you create a {CAGG} for a candlestick time
bucket, and then query the aggregate with different refresh policies. Finally,
you can use Grafana to visualize your data as a candlestick chart.
### Create a continuous aggregate
To look at OHLCV values, the most effective way is to create a {CAGG}. In this tutorial, you create a {CAGG} to aggregate data
for each day. You then set the aggregate to refresh every day, and to aggregate
the last two days' worth of data.
1. Connect to the {SERVICE_LONG} that contains the Twelve Data
cryptocurrency dataset.
2. At the psql prompt, create the {CAGG} to aggregate data every
day:
```sql theme={"dark"}
CREATE MATERIALIZED VIEW one_day_candle
WITH (timescaledb.continuous) AS
SELECT
time_bucket('1 day', time) AS bucket,
symbol,
FIRST(price, time) AS "open",
MAX(price) AS high,
MIN(price) AS low,
LAST(price, time) AS "close",
LAST(day_volume, time) AS day_volume
FROM crypto_ticks
GROUP BY bucket, symbol;
```
When you create the {CAGG}, it refreshes by default.
3. Set a refresh policy to update the {CAGG} every day,
if there is new data available in the {HYPERTABLE} for the last two days:
```sql theme={"dark"}
SELECT add_continuous_aggregate_policy('one_day_candle',
start_offset => INTERVAL '3 days',
end_offset => INTERVAL '1 day',
schedule_interval => INTERVAL '1 day');
```
### Query the continuous aggregate
When you have your {CAGG} set up, you can query it to get the
OHLCV values.
1. Connect to the {SERVICE_LONG} that contains the Twelve Data
cryptocurrency dataset.
2. At the psql prompt, use this query to select all Bitcoin OHLCV data for the
past 14 days, by time bucket:
```sql theme={"dark"}
SELECT * FROM one_day_candle
WHERE symbol = 'BTC/USD' AND bucket >= NOW() - INTERVAL '14 days'
ORDER BY bucket;
```
The result of the query looks like this:
```sql theme={"dark"}
bucket | symbol | open | high | low | close | day_volume
------------------------+---------+---------+---------+---------+---------+------------
2022-11-24 00:00:00+00 | BTC/USD | 16587 | 16781.2 | 16463.4 | 16597.4 | 21803
2022-11-25 00:00:00+00 | BTC/USD | 16597.4 | 16610.1 | 16344.4 | 16503.1 | 20788
2022-11-26 00:00:00+00 | BTC/USD | 16507.9 | 16685.5 | 16384.5 | 16450.6 | 12300
```
## Connect Grafana to Tiger Cloud
To visualize the results of your queries, enable Grafana to read the data in your {SERVICE_SHORT}:
1. **Log in to Grafana**
In your browser, log in to either:
* Self-hosted Grafana: at `http://localhost:3000/`. The default credentials are `admin`, `admin`.
* Grafana Cloud: use the URL and credentials you set when you created your account.
2. **Add your {SERVICE_SHORT} as a data source**
1. Open `Connections` > `Data sources`, then click `Add new data source`.
2. Select `PostgreSQL` from the list.
3. Configure the connection:
* `Host URL`, `Database name`, `Username`, and `Password`
Configure using your [connection details][connection-info]. `Host URL` is in the format `:`.
* `TLS/SSL Mode`: select `require`.
* `PostgreSQL options`: enable `TimescaleDB`.
* Leave the default setting for all other fields.
4. Click `Save & test`.
Grafana checks that your details are set correctly.
[cloud-login]: https://console.cloud.timescale.com/
[connection-info]: /integrations/find-connection-details
[create-service]: /deploy-and-operate/tiger-cloud/get-started/create-services
[grafana-cloud]: https://grafana.com/get/
[grafana-self-managed]: https://grafana.com/get/?tab=self-managed
## Graph OHLCV data
When you have extracted the raw OHLCV data, you can use it to graph the result
in a candlestick chart, using Grafana.
1. In Grafana, from the `Dashboards` page, click `New` and select `New dashboard`.
2. Click `Add visualization`, then select the data source that connects to your {SERVICE_LONG} and the `Candlestick` visualization type in the top right.
3. In the `Queries` section, select `Code` and paste the query you used to get the OHLCV values:
```sql theme={"dark"}
SELECT * FROM one_day_candle
WHERE symbol = 'BTC/USD' AND bucket >= NOW() - INTERVAL '14 days'
ORDER BY bucket;
```
4. Adjust elements of the table as required, and click `Apply` to save your
graph to the dashboard.

[bot]: https://www.tigerdata.com/blog/how-i-power-a-successful-crypto-trading-bot-with-timescaledb
[caggs]: /manage-data/data-management/continuous-aggregates/understand-continuous-aggregates
[first]: /api-reference/timescaledb/hyperfunctions/time-series-utilities/first
[grafana-cloud]: https://grafana.com/get/
[grafana-self-managed]: https://grafana.com/get/?tab=self-managed
[hyperfunctions]: /api-reference/timescaledb/hyperfunctions/
[ingest-real-time-financial-data]: /tutorials/ingest-real-time-financial-data
[last]: /api-reference/timescaledb/hyperfunctions/time-series-utilities/last
[messari]: https://www.tigerdata.com/blog/how-messari-uses-data-to-open-the-cryptoeconomy-to-everyone
[time-bucket]: /api-reference/timescaledb/hyperfunctions/time-series-utilities/time_bucket
[trading-strategy]: https://www.tigerdata.com/blog/how-trading-strategy-built-a-data-stack-for-crypto-quant-trading
[twelve-data]: https://twelvedata.com/